Power Analysis for DTC Holdout Experiments With Small Traffic Volumes
Holdout experiments for small DTC brands require power analysis before setting traffic splits.
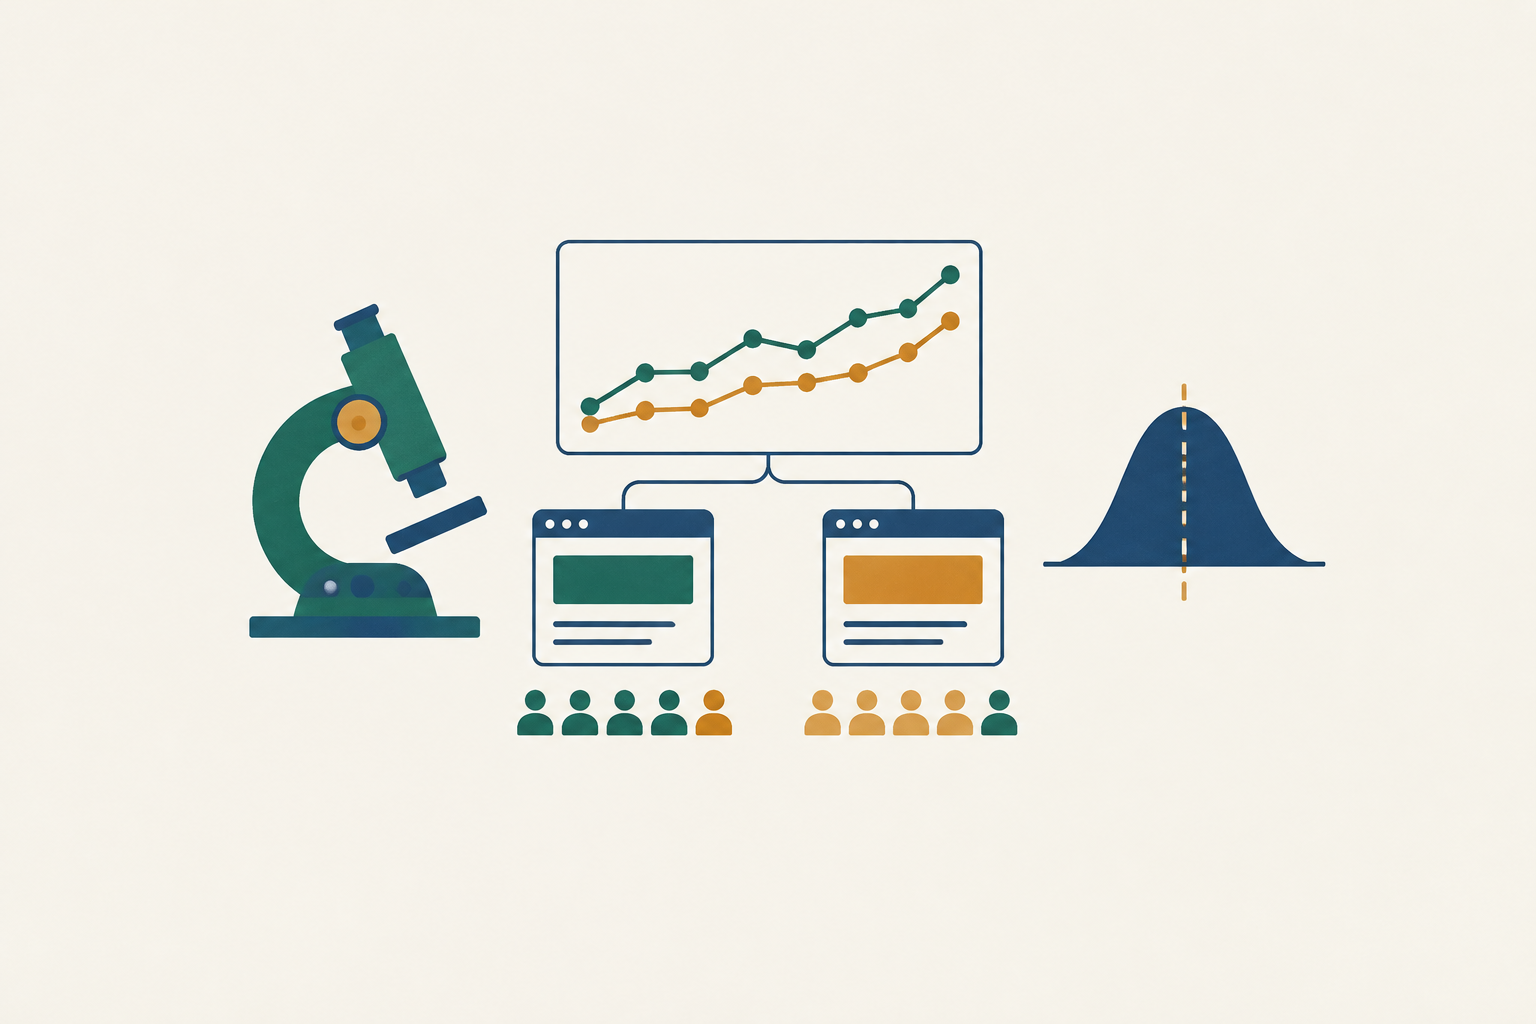
A valid DTC holdout experiment starts with power analysis before choosing a traffic split. For stores with only a few thousand monthly visitors, incrementality measurement they can trust depends on a clear trade-off between detectable lift, holdout size, and how long the test runs. The right design uses enough data to test an effect large enough to change a budget decision while there is still time to act on it.
Why platform attribution fails small DTC brands and what a holdout actually measures
Platform-reported ROAS conflates correlation with causation when a channel receives credit for purchases that would have happened anyway. That underlying purchase intent is baseline demand. Branded search and retargeting are especially prone to this because they reach people who already intend to buy, taking credit for orders driven by organic search, direct traffic, or brand loyalty. For a small brand, spending on those channels at the expense of ones that help drive purchases cuts into margin.
A holdout replaces attributed credit with a counterfactual. Eligible users are randomly assigned to an exposed group or a no-exposure control, and the difference in purchase outcomes estimates causal lift. Credibility depends on randomization, a genuine counterfactual rather than a before-and-after comparison, and a pre-registered primary metric. Quikly’s incrementality guide distinguishes gross lift, net lift, and incremental ROAS, terms operators should understand before designing the experiment.
The statistical ceiling that makes low-traffic holdouts fundamentally different
Power analysis uses baseline conversion rate, minimum detectable effect, significance level, and statistical power to work out how large the sample needs to be. MDE is the lift the test is designed to detect. Alpha sets the tolerated false-positive risk, while power describes the probability of detecting an effect of the specified size when it exists. Sample size is the number of experimental units needed to meet those conditions.
These inputs impose a steep constraint on feasibility. Halving the MDE roughly quadruples the required sample. At a 2% baseline conversion rate, detecting a 20% relative lift requires roughly 25,000 users per group at 80% power and 95% confidence. A store with a few thousand monthly visitors usually cannot gather that sample in time for the result to help the business.
A small control group can therefore be operationally convenient but commercially unreadable. Configuration is not evidence that a design is adequate. The greater danger is a test declared successful because significance appeared briefly and the team stopped, rather than because a pre-specified stopping condition was met. Power analysis must precede withholding users.
Setting the minimum detectable effect from unit economics, not from what feels achievable
The decision rule is to identify the minimum profit improvement that would change a budget allocation, then translate it into the primary metric’s required lift. Admetrics’ 2026 A/B benchmarks recommend starting with how much CAC needs to fall or contribution margin per session needs to rise, then checking whether the store has enough traffic to test for that effect.
Incremental ROAS provides the commercial anchor, while revenue per visitor or incremental margin per session can provide the sizing metric. Conversion lift alone is not enough if current AOV and COGS mean that contribution margin stays the same. On the other hand, a gain that is worth having but very small may need more traffic than the brand can gather before conditions change.
When traffic cannot support the economically relevant MDE, lowering it only increases the required sample size. The practical response is to test bigger changes with a larger MDE, while remaining explicit about the smaller effects the experiment will miss.
If a lift in revenue per session at your chosen MDE would not change how you allocate next quarter’s budget, your MDE is set too low.
Choosing between 80% and 90% power and what each choice costs
Power is a deliberate choice about false-negative risk. At 80% power, the test will miss one in five true effects of the size it was designed to detect. For a brand running only a handful of experiments each year, those misses can influence substantial budget decisions. A null result from an underpowered test can lead to cutting a genuinely incremental channel.
WarpDriven’s 2025 holdout best practices recommend 80–90% power at 5% alpha for realistic lift in triggered-flow holdouts. The choice depends on the decision’s consequences. An 80% target is defensible for a small creative variation, while 90% is the more appropriate standard for a test determining whether a channel remains in the media plan.
Higher power needs a larger sample, so greater confidence in the same data alone will not deliver it. That cost can make a feasible test impractical. Operators should calculate the sample requirement at both settings before choosing, then document the selected power with the hypothesis and stopping rule. The trade-off is between missing a real effect and funding a longer or larger experiment.
Holdout size as a percentage of traffic and the revenue cost of withholding too much
A 20% holdout on a store with 3,000 monthly visitors leaves 600 users in control. At a 2% conversion rate, that produces roughly 12 control conversions per month, insufficient for most commercially meaningful effects over a short window. The percentage looks substantial. The outcome count is sparse.
The disciplined approach works backward from power and MDE to the required allocation. If that calculation requires withholding 40% of traffic for four months, the response is to reconsider the MDE, duration, or experimental unit and check whether a smaller split will suffice. The opportunity cost depends on how strongly the intervention is already believed to work and the suspected effect’s size.
Triggered email and push flows face a tighter constraint because eligible users are only a subset of store traffic. CUPED, a variance-reduction method, uses pre-experiment behavior to reduce outcome variance, increasing power without increasing sample size. Low-traffic brands should ask whether their experimentation tools support it before accepting a larger holdout as the only option.
Test duration, seasonality windows, and when to stop
Duration must accommodate both sample accumulation and purchase behavior. Two to four weeks is a common ecommerce baseline, but the brand’s median days-to-conversion should determine the minimum window. Longer consideration cycles require more time than impulse purchases. Extending indefinitely, however, risks mixing the intervention’s effect with seasonal shifts, major promotions, or changes in competitive conditions.
Admetrics cautions against ending immediately after a promotional spike or payday weekend, when unusual demand can dominate the result. The stopping rule must be set before the test starts. It can specify a sample horizon or use a sequential test with pre-specified alpha-spending, rather than stopping whenever p < 0.05. WarpDriven recommends disabling Braze’s Winning Path during the initial lift test because it changes allocation after a pre-set experiment window.
For some low-traffic stores, adequate sample collection implies three to six months of runtime. That may be commercially unacceptable or cross unsuitable measurement windows. In that case, the available responses are a larger MDE, a geo holdout, or acknowledging that a valid user-level experiment must wait for more traffic.
Geo holdouts as the practical workaround for user-level power constraints
Geo holdouts group revenue by market rather than user, which can give each experimental unit a stronger signal if enough revenue comes from that market. Geography becomes the unit of randomization instead. This can reduce household spillover between exposed and unexposed users, but introduces regional promotions, weather, and competitor activity as potential confounders.
State-level tests collect more revenue within each unit, while DMA-level designs typically offer more units, more homogeneous populations, and finer control over external variables. But DMA designs can still need bigger budgets or more time. Quikly notes that geo experiments need to account for more than gross outcome differences because it is harder to keep conditions alike across markets.
Operators should assess pre-period correlation between candidate holdout and comparison markets before committing to the design, since markets that do not move together historically make a weak counterfactual. Stella’s 2025 DTC incrementality benchmark found that even across 225 tests, most business verticals lacked sufficient depth for robust vertical-level conclusions. A geo design can make a small-brand experiment workable without making its result broadly generalizable.
Variance reduction and pooling strategies when no single test design is sufficient alone
When user-level and geo designs each have too little power on their own, variance reduction and aggregation can make more of the signal usable. Their feasibility still needs investigation. WarpDriven recommends checking for native CUPED support before building a workaround, particularly for underpowered triggered-flow experiments. An experimentation platform can let teams use the method without having to build it themselves.
Trigger pooling puts similar flows into a shared holdout so more users are eligible without the store needing more traffic, as long as the flows are expected to have much the same effects. Pooling changes what the resulting estimate describes. A lifecycle automation estimate is not automatically evidence about each constituent flow. Sample ratio mismatch also requires an early chi-squared check, because an intended 80/20 split arriving as 72/28 can signal broken randomization and make the result untrustworthy regardless of its p-value.
Reading the result honestly: what a small-traffic holdout can and cannot prove
A valid small-traffic holdout estimates the effect of a given intervention during the window in which it runs. It cannot show what the channel’s return will be for all time. Confidence intervals should come with point estimates, and wide intervals should limit budget changes because they leave much of the effect’s size in doubt. Replication or a larger test is warranted before treating an imprecise estimate as a firm allocation rule.
Stella advises discounting benchmark iROAS because brands running structured incrementality tests are self-selected measurement sophisticates who may outperform the broader DTC population. Within a brand, repeated tests help reveal whether estimated returns are stable or volatile. A third holdout on the same channel is more informative than the first because it adds evidence across experimental selections and windows.
Quikly recommends choosing the primary outcome in advance, documenting secondary metrics, and recording guardrails such as refunds, unsubscribes, complaints, or profit. Those records keep good secondary results from taking the place of the original question after the test.
Your first holdout is a calibration exercise as much as a decision tool, run it for both the discipline it builds and the number it returns.
Building AI-readiness into the measurement stack before the next holdout runs
That discipline must extend to how purchase intent becomes visible. Shopify reports that AI-driven orders to its stores grew 15x from January to December 2025. AI shopping agents can influence purchases without leaving a browser-trackable referral, while AI-referred traffic frequently appears as “Direct” in GA4 and Shopify Analytics. A holdout may thus record the conversion without showing what helped drive the purchase earlier in either group.
Randomization remains appropriate despite this limited visibility. Monitoring branded search volume with holdout results can provide a proxy for influence that referral reporting misses. ChatGPT and Google AI Mode read machine-readable product information, while Perplexity and Gemini answer in prose, making weak schema markup and incomplete variant data a constraint on how accurately products are represented.
Before the next experiment, operators should audit structured data and AI-channel visibility while continuing to build holdout discipline. As more brands build this visibility, treating AI-channel measurement as an edge case becomes less defensible. The payoff is a more complete reading of purchase intent, more accurate future holdouts, and better AI campaigns.